I'm wondering why file size matters, because wouldn't the date be off by even a few seconds if it's two different copies of a file? Even in a high speed automated "log.txt" or something updated and then aggressively backed up, do any of the options above change context if it doesn't need to know the file size (or maybe checksum, because for ex someone opens a text file and then say MS Word adds a line break it's now different.)
_______________________
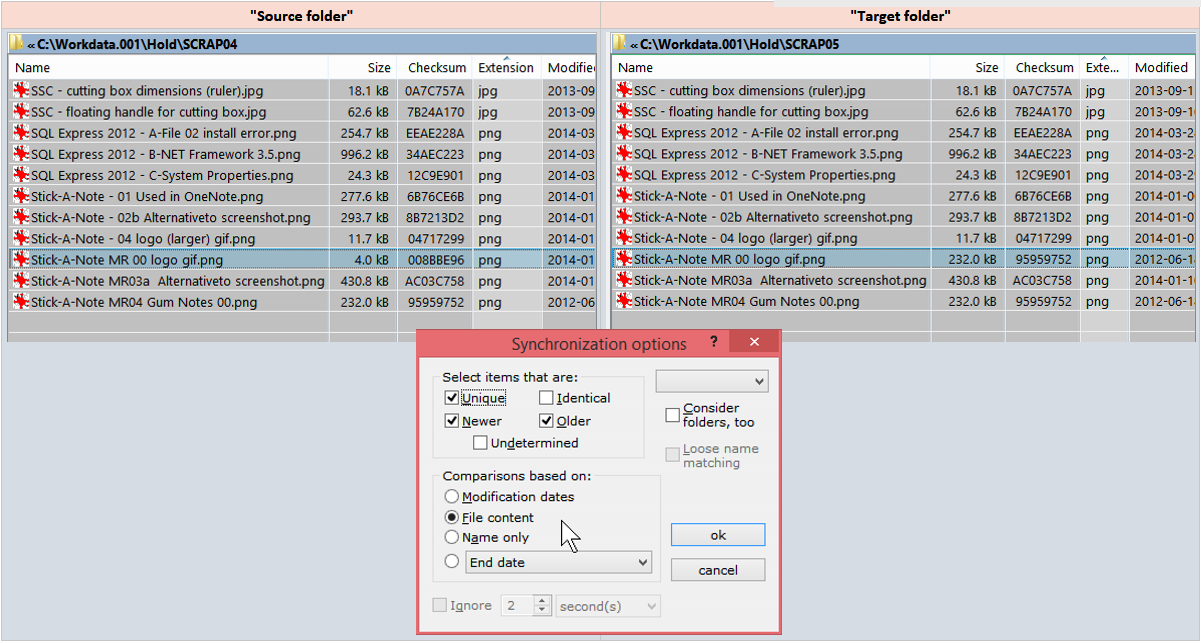
The OP refers to file "name, extension and size", but file size is generally an unreliable/imprecise basis for file comparison, whereas content (checksum) is pretty definitive as a data analysis tool.
You seem to have conflated "time" with "size", and yes, "time" is also an imprecise basis for file comparison - mainly because of the different and inconsistent time-stamping standards applied by different file operations and file management tools.
Where you say "...do any of the options above change context if it doesn't need to know the file size (or maybe checksum, because for ex someone opens a text file and then say MS Word adds a line break it's now different.)" my response would be that the OP apparently has a redundant requirement in
Filter #1 (QED) and that my comments would seem to indicate that "size" is irrelevant (QED) and "checksum" is an imperative for file validation when housekeeping in cases such as this. It's not my opinion, it's just
Computer Operations Housekeeping Best Practice 101 and is typically the sort of thing that would be drilled into you in programmer training if you worked for a computer company. It is also strongly justified as being a forensic and prudent measure in its own right.
And yes, the checksum comparison
would show a difference between file A and file B, where file B was the result where (say) "...someone opens a text file and then say MS Word adds a line break it's now different.", but that's not the case here. In this case, A and B are apparently identical in ""name, extension and size" and presumed identical, but we know that size is unreliable and so we need to verify
whether they are identical in fact, and the only valid test we have there is
whether they are the same in content (checksum). Sure, a difference could be attributable to (say)
- (a) file corruption on write, or after having been written (e.g., if there had been a disk surface or other media degradation),
- (b) a virus infection update,
- (c) an MS Word update of the type you describe.
- but in this case I think there is an implicit assumption that the possibilities for (b) and/or (c) would have been eliminated before this backup amalgamation/rationalisation stage. However, if that is an invalid assumption, then the problem expands to one of entire database verification and validation,
prior to going further with backup amalgamation/rationalisation. You have to start with clean source data otherwise you can forget about backups as they become largely irrelevant.
My understanding from the OP is that the files in Source are effectively taken as being the clean master version of the files in
Filter #1, and any duplicate files in Target are some kind of copy (e.g., backup copy) of the master files.