How about mirroring the entire site and then picking out the page/pages you want?
"HTTrack is a free (GPL, libre/free software) and easy-to-use offline browser utility...
If you're doing research on the web and darting around from site to site, mirroring entire sites isn't really practical. Take the sample page I used for the test in the first post -- I can't begin to imagine how many thousands of pages there are on the BBC News site.
No, for web research, grabbing single pages as you go is really the only efficient way to work.
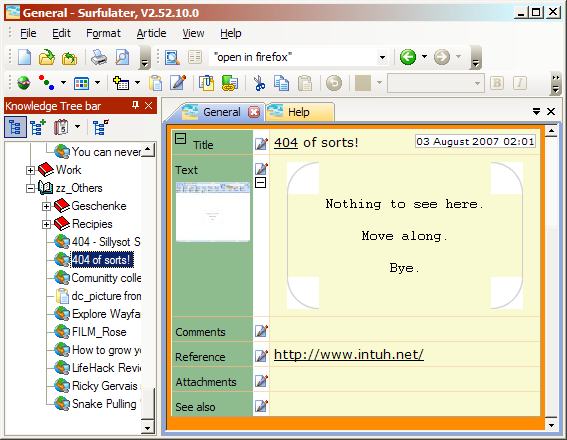
Since doing the test, I've come at it from another angle -- I've been having a play with the web research "specialists", Local Website Archive (LWA) and WebResearch Pro (WRP) to see if they could compete with Ultra Recall and Surfulater as "data dumps".
WRP is the more fully-featured, and has the nicer, glossier UI. But it seems very low on the radar -- you see very little discussion about it on the web. And they don't have a user forum on their site, which always gets a black mark from me. One of the big features in the latest version is that its database format is supported by Windows Search, but I had problems getting the two to work reliably together. And my last two emails to their support department went unanswered...
LWA is a more spartan affair, but it does what it says on the tin. And with a bit of tweaking, you can add documents from a variety of sources including plain text and html, and edit them which makes it a possible all-round "data dump" for research purposes, on a small scale.
Of course LWA was never intended for such a purpose. It's a web page archive, pure and simple, and a good one. You can add notes to entries. The database is simply separate html and related files for each item. Files and content are not indexed for search. LWA doesn't have tags/categories (WRP does) so you're stuck with folders. And as LWA keeps file information (metadata) and file content in different places, it's problematic for desktop search programs to analyze it unless they know about the structure (I've already asked the Archivarius team if they'll support the LWA database structure).
LWA may be a keeper though...